
5.4: Understanding Statistical Graphs and Tables
- Page ID
- 203111
\( \newcommand{\vecs}[1]{\overset { \scriptstyle \rightharpoonup} {\mathbf{#1}} } \)
\( \newcommand{\vecd}[1]{\overset{-\!-\!\rightharpoonup}{\vphantom{a}\smash {#1}}} \)
\( \newcommand{\dsum}{\displaystyle\sum\limits} \)
\( \newcommand{\dint}{\displaystyle\int\limits} \)
\( \newcommand{\dlim}{\displaystyle\lim\limits} \)
\( \newcommand{\id}{\mathrm{id}}\) \( \newcommand{\Span}{\mathrm{span}}\)
( \newcommand{\kernel}{\mathrm{null}\,}\) \( \newcommand{\range}{\mathrm{range}\,}\)
\( \newcommand{\RealPart}{\mathrm{Re}}\) \( \newcommand{\ImaginaryPart}{\mathrm{Im}}\)
\( \newcommand{\Argument}{\mathrm{Arg}}\) \( \newcommand{\norm}[1]{\| #1 \|}\)
\( \newcommand{\inner}[2]{\langle #1, #2 \rangle}\)
\( \newcommand{\Span}{\mathrm{span}}\)
\( \newcommand{\id}{\mathrm{id}}\)
\( \newcommand{\Span}{\mathrm{span}}\)
\( \newcommand{\kernel}{\mathrm{null}\,}\)
\( \newcommand{\range}{\mathrm{range}\,}\)
\( \newcommand{\RealPart}{\mathrm{Re}}\)
\( \newcommand{\ImaginaryPart}{\mathrm{Im}}\)
\( \newcommand{\Argument}{\mathrm{Arg}}\)
\( \newcommand{\norm}[1]{\| #1 \|}\)
\( \newcommand{\inner}[2]{\langle #1, #2 \rangle}\)
\( \newcommand{\Span}{\mathrm{span}}\) \( \newcommand{\AA}{\unicode[.8,0]{x212B}}\)
\( \newcommand{\vectorA}[1]{\vec{#1}} % arrow\)
\( \newcommand{\vectorAt}[1]{\vec{\text{#1}}} % arrow\)
\( \newcommand{\vectorB}[1]{\overset { \scriptstyle \rightharpoonup} {\mathbf{#1}} } \)
\( \newcommand{\vectorC}[1]{\textbf{#1}} \)
\( \newcommand{\vectorD}[1]{\overrightarrow{#1}} \)
\( \newcommand{\vectorDt}[1]{\overrightarrow{\text{#1}}} \)
\( \newcommand{\vectE}[1]{\overset{-\!-\!\rightharpoonup}{\vphantom{a}\smash{\mathbf {#1}}}} \)
\( \newcommand{\vecs}[1]{\overset { \scriptstyle \rightharpoonup} {\mathbf{#1}} } \)
\(\newcommand{\longvect}{\overrightarrow}\)
\( \newcommand{\vecd}[1]{\overset{-\!-\!\rightharpoonup}{\vphantom{a}\smash {#1}}} \)
\(\newcommand{\avec}{\mathbf a}\) \(\newcommand{\bvec}{\mathbf b}\) \(\newcommand{\cvec}{\mathbf c}\) \(\newcommand{\dvec}{\mathbf d}\) \(\newcommand{\dtil}{\widetilde{\mathbf d}}\) \(\newcommand{\evec}{\mathbf e}\) \(\newcommand{\fvec}{\mathbf f}\) \(\newcommand{\nvec}{\mathbf n}\) \(\newcommand{\pvec}{\mathbf p}\) \(\newcommand{\qvec}{\mathbf q}\) \(\newcommand{\svec}{\mathbf s}\) \(\newcommand{\tvec}{\mathbf t}\) \(\newcommand{\uvec}{\mathbf u}\) \(\newcommand{\vvec}{\mathbf v}\) \(\newcommand{\wvec}{\mathbf w}\) \(\newcommand{\xvec}{\mathbf x}\) \(\newcommand{\yvec}{\mathbf y}\) \(\newcommand{\zvec}{\mathbf z}\) \(\newcommand{\rvec}{\mathbf r}\) \(\newcommand{\mvec}{\mathbf m}\) \(\newcommand{\zerovec}{\mathbf 0}\) \(\newcommand{\onevec}{\mathbf 1}\) \(\newcommand{\real}{\mathbb R}\) \(\newcommand{\twovec}[2]{\left[\begin{array}{r}#1 \\ #2 \end{array}\right]}\) \(\newcommand{\ctwovec}[2]{\left[\begin{array}{c}#1 \\ #2 \end{array}\right]}\) \(\newcommand{\threevec}[3]{\left[\begin{array}{r}#1 \\ #2 \\ #3 \end{array}\right]}\) \(\newcommand{\cthreevec}[3]{\left[\begin{array}{c}#1 \\ #2 \\ #3 \end{array}\right]}\) \(\newcommand{\fourvec}[4]{\left[\begin{array}{r}#1 \\ #2 \\ #3 \\ #4 \end{array}\right]}\) \(\newcommand{\cfourvec}[4]{\left[\begin{array}{c}#1 \\ #2 \\ #3 \\ #4 \end{array}\right]}\) \(\newcommand{\fivevec}[5]{\left[\begin{array}{r}#1 \\ #2 \\ #3 \\ #4 \\ #5 \\ \end{array}\right]}\) \(\newcommand{\cfivevec}[5]{\left[\begin{array}{c}#1 \\ #2 \\ #3 \\ #4 \\ #5 \\ \end{array}\right]}\) \(\newcommand{\mattwo}[4]{\left[\begin{array}{rr}#1 \amp #2 \\ #3 \amp #4 \\ \end{array}\right]}\) \(\newcommand{\laspan}[1]{\text{Span}\{#1\}}\) \(\newcommand{\bcal}{\cal B}\) \(\newcommand{\ccal}{\cal C}\) \(\newcommand{\scal}{\cal S}\) \(\newcommand{\wcal}{\cal W}\) \(\newcommand{\ecal}{\cal E}\) \(\newcommand{\coords}[2]{\left\{#1\right\}_{#2}}\) \(\newcommand{\gray}[1]{\color{gray}{#1}}\) \(\newcommand{\lgray}[1]{\color{lightgray}{#1}}\) \(\newcommand{\rank}{\operatorname{rank}}\) \(\newcommand{\row}{\text{Row}}\) \(\newcommand{\col}{\text{Col}}\) \(\renewcommand{\row}{\text{Row}}\) \(\newcommand{\nul}{\text{Nul}}\) \(\newcommand{\var}{\text{Var}}\) \(\newcommand{\corr}{\text{corr}}\) \(\newcommand{\len}[1]{\left|#1\right|}\) \(\newcommand{\bbar}{\overline{\bvec}}\) \(\newcommand{\bhat}{\widehat{\bvec}}\) \(\newcommand{\bperp}{\bvec^\perp}\) \(\newcommand{\xhat}{\widehat{\xvec}}\) \(\newcommand{\vhat}{\widehat{\vvec}}\) \(\newcommand{\uhat}{\widehat{\uvec}}\) \(\newcommand{\what}{\widehat{\wvec}}\) \(\newcommand{\Sighat}{\widehat{\Sigma}}\) \(\newcommand{\lt}{<}\) \(\newcommand{\gt}{>}\) \(\newcommand{\amp}{&}\) \(\definecolor{fillinmathshade}{gray}{0.9}\)Understanding Bar Graph
A bar chart is a visualization of categorical data that consists of a series of rectangles arranged side by side (but not touching). Each rectangle corresponds to a category. All of the rectangles have the same width. The height of each rectangle corresponds to either the number of units in the corresponding category or the proportion of the total units that fall into the category.
Example \(\PageIndex{1}\): Understand Bar Graph
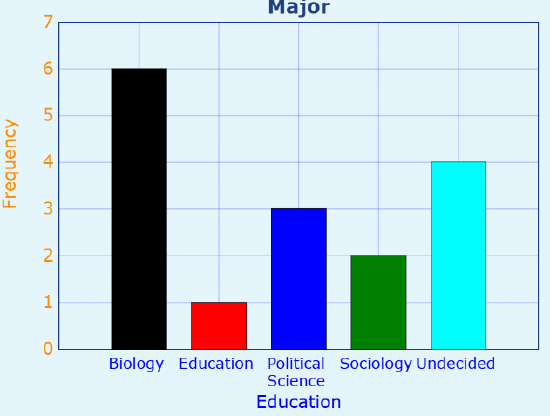
Students in a statistics class were asked to list their majors. A bar graph is drawn to visualize this data. Answer the following questions.
- How many people participated in the survey?
- How many more people plan to major in Biology than in Education?
- Is the data on the horizontal axis categorical or quantitative?
- Is this graph a bar chart, a histogram, or a Pareto chart?
- What is the proportion of students who plan to major in Education?
- What percentage of students are unsure about their major?
- Answer
-
- \(6+1+3+2+4=16\)
- \(6-1=5\) More students majoring in Biology than in Education.
- Categorical (Qualitative)
- Not Histogram. Not a Pareto chart.
- \(\frac{1}{16}=0.0625\)
- \(\frac{4}{16}=0.25=25\%\)
Your Turn \(\PageIndex{1}\): Average Monthly Precipitation
If the data we’re visualizing is categorical, we want a quick way to graphically represent the relative numbers of units in each category. When we created the frequency distributions in the last section, we simply counted the number of units in each category and recorded that count (the frequency of that category). Frequencies are nice when we’re organizing and summarizing data; they’re easy to compute, and they’re always whole numbers. But they can be difficult to understand for an outsider who’s being introduced to your data.
Let’s get some practice reading bar graphs.
Example \(\PageIndex{2}\): Reading Bar Graph
The bar graph shown gives data on \(2020\) model year cars available in the United States. Analyze the graph to answer the following questions.
- What proportion of available cars were sports cars?
- What proportion of available cars were sedans?
- Which categories of cars each made up less than \(5\%\) of the models available?
- Answer
-
- The bar for sports cars goes up to \(10\%\), so the proportion of models that are considered sports cars is 10%.
- The bar corresponding to sedan goes up past \(30\%\) but not quite to \(35\%\). It looks like the proportion we want is between \(33\%\) and \(34\%\).
- We’re looking for the bars that don’t make it all the way to the \(5\%\) line. Those categories are hatchback and wagon.
Understanding Pie Charts
A pie chart consists of a circle divided into wedges, with each wedge corresponding to a category. The proportion of the area of the entire circle that each wedge represents corresponds to the proportion of the data in that category. Pie charts are difficult to create without technology because they require careful angle measurements and precise circles, both of which are tasks better suited to computers.
Example \(\PageIndex{4}\): Construct Bar Graph
Use the data that follows to generate a pie chart.
| Type | Percent | Type | Percent |
|---|---|---|---|
| SUV | 43.6% | Minivan | 5.5% |
| Sedan | 33.6% | Hatchback | 3.6% |
| Sports | 10.0% | Wagon | 3.6% |
- Answer
-
First, enter the chart above into a new sheet in Google Sheets. Next, click and drag to select the full table (including the header row). Click on the “Insert” menu, then select “Chart.” The result may be a pie chart by default; if it isn’t, you can change it to a pie chart using the “Chart type” drop-down menu in the Chart Editor.
Figure \(\PageIndex{4}\) (data source: consumerreports.org/cars)You can choose to use a legend to identify the categories, as well as label the slices with the relevant percentages.
Florence Nightingale (1820–1910) is best remembered today for her contributions in the medical field; after witnessing the horrors of field hospitals that tended to the wounded during the Crimean War, she championed reforms that encouraged sanitary conditions in hospitals. For those efforts, she is today considered the founder of modern nursing.
Figure \(\PageIndex{5}\): Florence Nightingale's significant contribution to the field of statistical graphics cannot be understated. (credit: "Florence Nightingale" by Library of Congress Prints and Photographs Division/Library of Cogress(opens in new window) [hdl.loc.gov], public domain)Nightingale is also remembered for her contributions in statistics, especially in the ways we visualize data. She developed a version of the pie chart that is today known as a polar area diagram, which she used to visualize the causes of death among the soldiers in the war, highlighting the number of preventable deaths the British Army suffered in that conflict.In 1859, the Royal Statistical Society honored her for her contributions to the discipline by electing her to join the organization. She was the first woman to be so honored. She was later named an honorary member of the American Statistical Association. Nightingale's status as a revered pioneer in both nursing and statistics is a complex one, because some of her writings and opinions demonstrate a colonialist mindset and disregard for those who lost their lives and lands at the hands of the British. Her core statistical writings indicated that she felt superior to the Indigenous people she was treating. Members of both fields continue to debate her near-iconic role.
Understating Histogram
As we see in the previous section, there are four distributions that describe quantitative data. They are: uniform (data are equally distributed across the range), symmetric (data are bunched up in the middle, then taper off in the same way above and below the middle), left-skewed (data are bunched up at the high end or larger values, and taper off toward the low end or smaller values), and right-skewed (data are bunched up at the low end, and taper off toward the high end). See below figures.
\(\PageIndex{6}\): Distribution of Histogram
Looking back at the stem-and-leaf plot in the previous example, we can see that the data are bunched up at the low end and taper off toward the high end; that set of data is right-skewed. Knowing the distribution of a set of data gives us useful information about the property that the data are measuring.
Example \(\PageIndex{6}\): Find Information from Histogram
The data in “AvgSAT”(opens in new window) contains the average SAT score for students attending every institution of higher learning in the US for which data is available. Create a histogram in Google Sheets of the average SAT scores. Use bins of width \(50\). Are the data uniformly distributed, symmetric, left-skewed, or right-skewed?
- Answer
-
The data are fairly symmetric, but slightly right-skewed.
Misleading Graphs
Graphical representations of data can be manipulated to intentionally mislead the reader. There are two primary ways this can be done: by adjusting the scales on the axes and by manipulating or misrepresenting the areas of the bars. Let’s look at some examples of these.
Example \(\PageIndex{9}\): Misleading Bar Graph
The table below shows the teams and their payrolls in the English Premier League, the top soccer organization in the United Kingdom.
How might someone present this data in a misleading way?
- Answer
-
You should notice that despite using the same data, these two graphs look strikingly different. In the second graph, the gap between Manchester United and the other four teams appears significantly larger than in the first. The scale on the vertical axis has been manipulated here. The first graph's axis starts at zero, while the lowest value on the second graph's axis is \(120\). This trick has a strong impact on the viewer’s perception of the data.
Beware of infographics! Areas overemphasize a difference that should be measured with a height!
Now, let’s look at all 20 teams. This histogram indicates that the data are right-skewed, with the highest number of teams having a payroll between £40 million and £80 million:
Even though this chart uses the same data, the skew seems to be reversed. Why? Well, even though this graph looks like a histogram, it isn’t. Look closely at the labels on the horizontal axis; they don't correspond to spots on the axis, but instead provide a range, meaning this is a bar graph based on a binned frequency distribution.
When we review these ranges, we can see that the last range is misleading as it consists of all data “over \(80\).” If the bins all had the same width, that last bin would run from \(80\) to \(120\). However, the histogram shows that the maximum value for this data is between \(160\) and \(200\). If the last bin in this bar graph were labeled honestly, it would read “\(80–200\),” which would drive home the fact that the bar's width is misleading.
Always check the horizontal axis on histograms! The widths of all the bars should be equal.
Minard’s chart is remarkable in that it shows not only how the size of Napoleon’s army shrank drastically over time, but also its location on the map, the direction it was traveling at the time, and the temperature during the retreat.
Example \(\PageIndex{10}\): Misleading Bar Graph
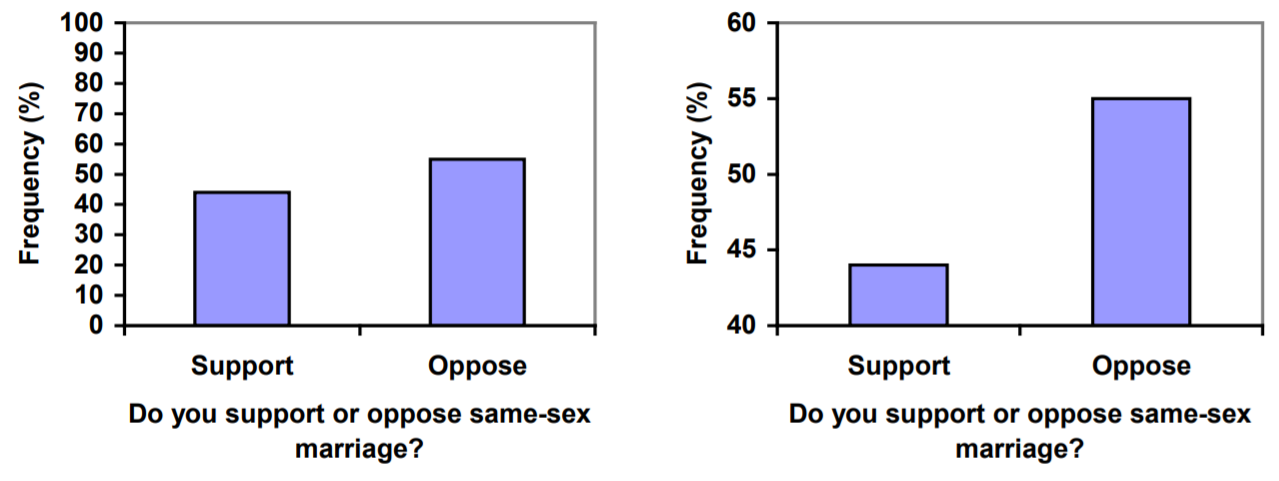
Compare the two graphs below showing support for same-sex marriage rights from a poll taken in December \(2008\) [3]. The difference in the vertical scale on the first graph suggests a different story than the true differences in percentages; the second graph makes it appear as though twice as many people oppose marriage rights as support them.